Background Large language model (LLM)–based tools are increasingly used to automate risk-of-bias assessment of randomized controlled trials with the revised Cochrane tool (RoB 2.0). However, their reproducibility, their accuracy, and their fidelity to the deterministic algorithm mapping signalling-question responses to domain judgments remain unclear.
Methods In a conference workshop, participants used an identical prompt and tool versions to assess one RCT with three configurations and entered each tool’s output verbatim (13, 15, and 10 runs). One experienced reviewer’s assessment served as the reference. For each run we computed run-to-run reproducibility, agreement with the expert, and conformance between the tool’s stated domain judgment and the judgment implied by applying the RoB 2.0 algorithm to that run’s own signalling answers.
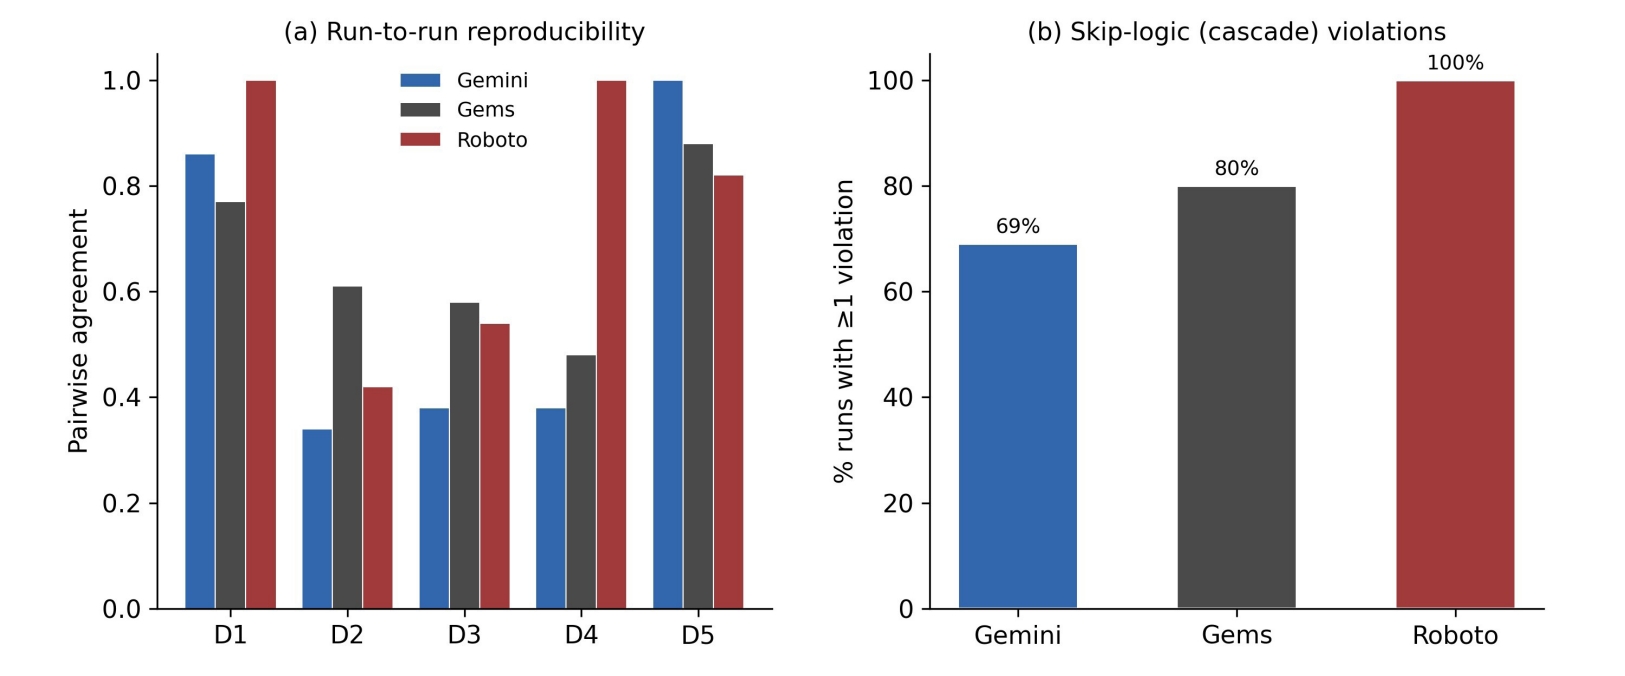
Results All configurations showed substantial run-to-run variability under identical conditions, greatest in the conditionally complex domain 2 (Gemini pairwise agreement 0.34). Expert agreement varied widely across configurations (mean 5–60%), and one configuration systematically under-rated risk. Even in domains with a fully specified algorithm, stated judgments frequently diverged from the value implied by the tool’s own signalling answers (domain 2, mean 42%). Skip-logic violations occurred in 69%, 80%, and 100% of runs. Recomputing domain judgments from the signalling answers improved expert agreement for the general-purpose configurations.
Conclusion LLM-based RoB 2.0 assessments exhibited variability and errors. Whatever tool is adopted, its characteristics and variability must be recognized. Having the tool perform only atomic (single) judgments while delegating aggregation to the algorithm, together with human review, may improve accuracy.

 First
 Prev